Workshop · Tech note #02 · personal project
LLM Advanced
Offline local AI with real math tools
A local AI platform on top of Ollama: chat, RAG, code generation and math and physics routes powered by SymPy, NumPy and SciPy. No cloud, no API key and SQLite by default.
AI that never leaves the machine
Many companies want to use LLMs but can’t send data outside; or the per-token cost rules out heavy internal use. LLM Advanced runs a complete API and interface on top of a local Ollama.
- No cloud and no API key
- Zero per-token cost: the model runs on your machine
- Works without internet, with a documented offline mode
The routes
The API has more than ten route groups. The main ones:
Chat
Talk to local models.
RAG
Questions about your own documents.
Math and physics
Dedicated routes that actually use SymPy, NumPy and SciPy, not just a prompt.
Code
Code generation.
Search and writing
Search and assisted writing.
Orchestrator
HTTP integration with other systems.
Architecture
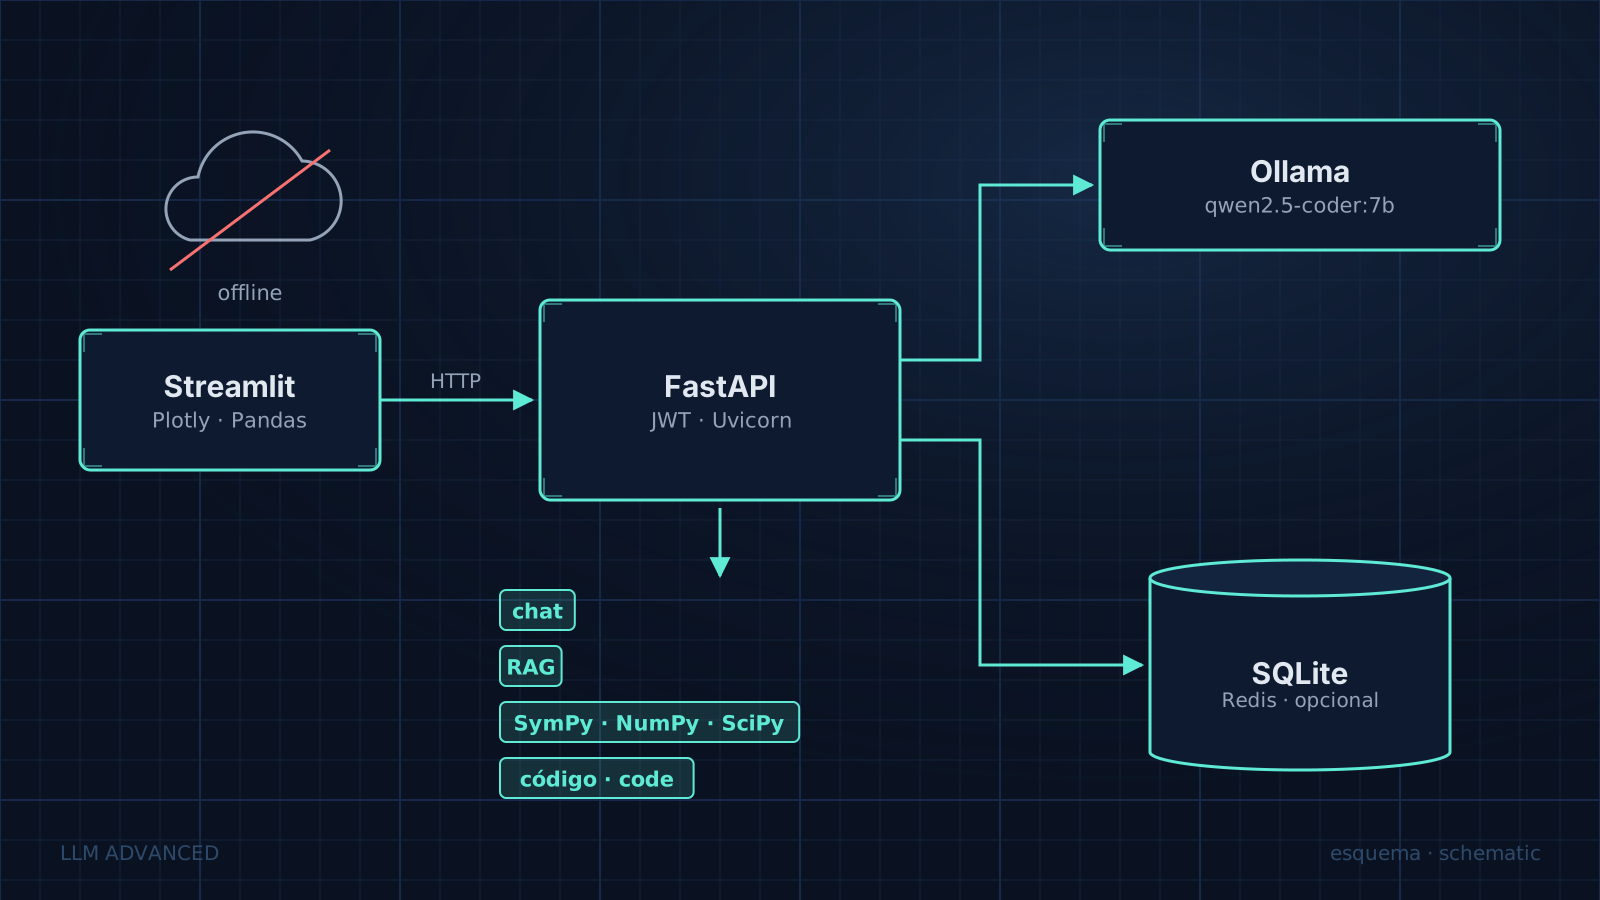
- Streamlit interface, with charts in Plotly, Pandas and Matplotlib.
- FastAPI + Uvicorn API, with JWT authentication and built-in monitoring.
- Ollama running the model locally.
- Data in SQLAlchemy + Alembic, with SQLite by default and optional Redis.
Run it anywhere
Without Docker
Starts with SQLite, no extra infrastructure.
With Docker Compose
Compose defaults to the qwen2.5-coder:7b model; llama3.2 is documented too.
Offline on Windows
Install and run scripts plus guides for local and offline use.
Tech sheet
- Python 3.11+
- FastAPI + Uvicorn
- SQLAlchemy + Alembic
- Streamlit
- Ollama
- SymPy · NumPy · SciPy
- JWT + passlib
- Docker Compose
- SQLite / Redis
- Status
- API with 10+ route groups, Streamlit front end, tests and roadmaps
- Default model
- qwen2.5-coder:7b (in Compose)
- Database
- SQLite by default; Redis optional
- Network
- Works offline
Need AI that keeps your data in-house? Let’s talk.
Write to me